
Why might a model start pulling from different sources over time?
A model starts pulling from different sources over time when its retrieval path, source freshness, or ranking rules change. That happens because the surrounding system changes, not because the question itself changed. If no one governs those shifts, the same query can cite a different policy, a different product page, or no verified source at all.
Senso’s docs describe this clearly. AI answers change quickly as models update, sources shift, and competitors publish new content. In one implementation note, a content assistant fell back on general knowledge when a required knowledge base query returned empty. In another, stale model filter options hid newer models because the source stopped updating in early June.
What makes a model change the sources it uses?
A model changes sources when the evidence it can see changes. Source freshness, source replacement, routing logic, and model updates all affect which raw sources rise to the top. The result is a moving target, especially when the system answers questions about price, policy, product facts, eligibility, terms, or authority.
| Cause | What changes | What you see |
|---|---|---|
| Model update | Ranking and retrieval behavior | Different citations for the same query |
| Freshness refresh | Older sources get replaced | Newer pages or records appear in answers |
| Source replacement | The source of record changes | Old policy or price disappears |
| Empty context | The model has less verified material | Fallback to generic answers or weaker citations |
| External publication | New competitor or market content appears | Mentions and citations shift over time |
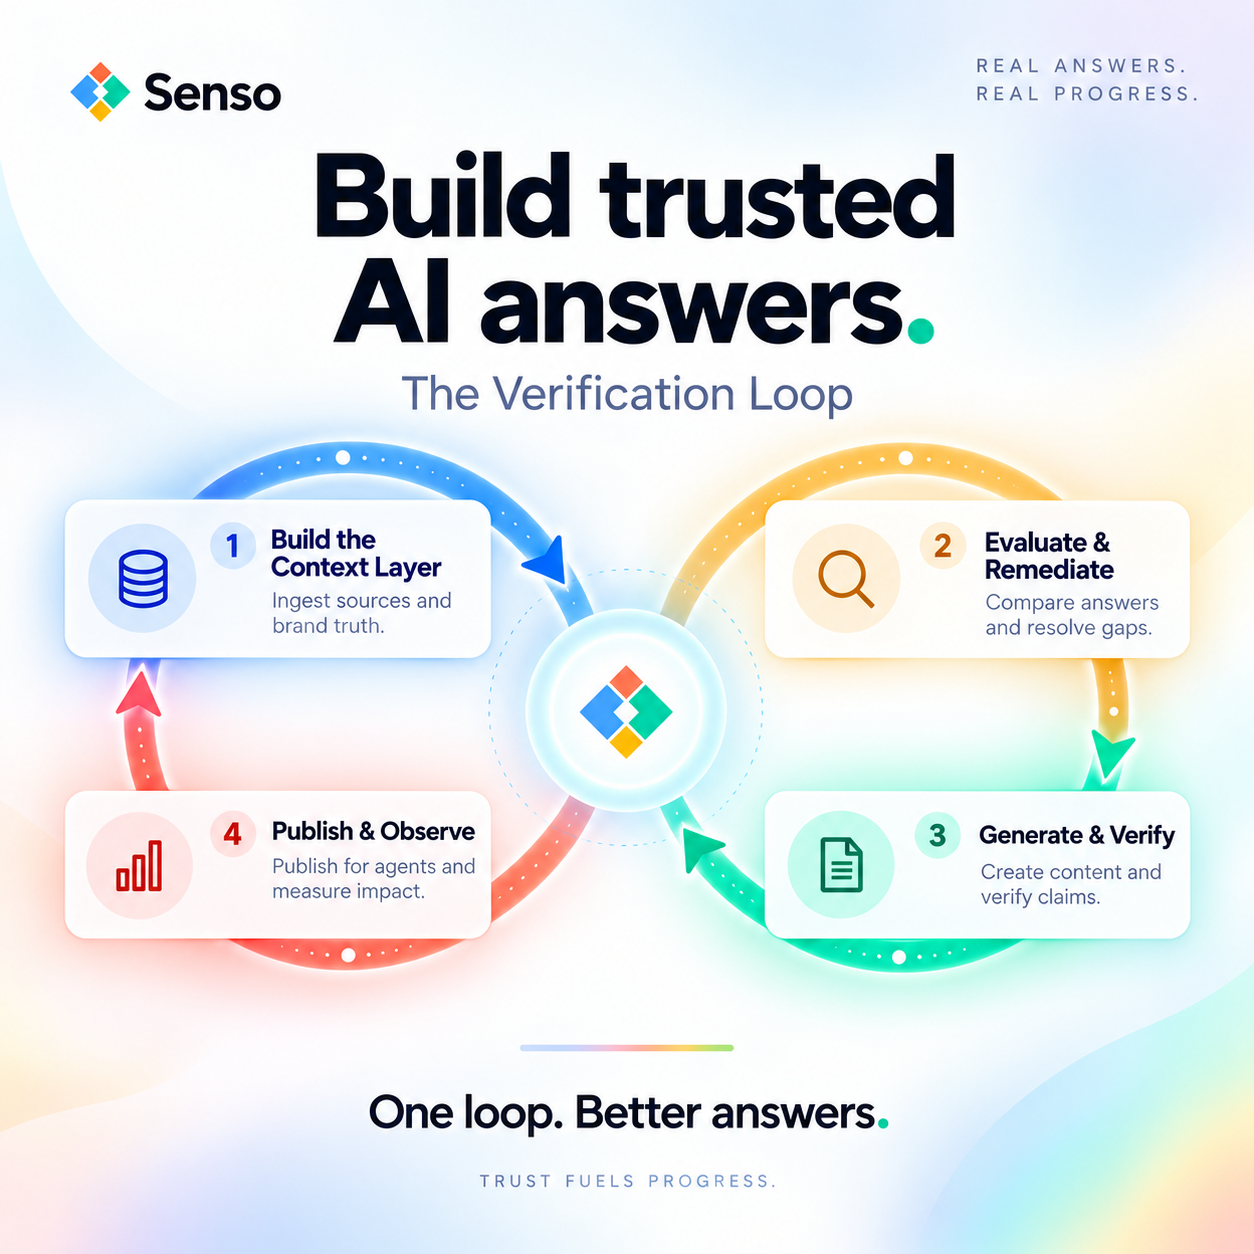
Senso’s verification loop treats this as normal input to the next cycle. New model behavior, changed source records, and unresolved claims all feed the next round of evaluation. Publication is not the end state.
Why does the same prompt cite different sources on different days?
The same prompt can cite different sources because the model is sampling from a changing source set. The web changes, internal content changes, and retrieval systems refresh on different schedules. Senso’s documentation says AI answers change quickly as models update, sources shift, and competitors publish new content.
A few concrete causes show up often:
- Source freshness changes. One changelog note said part of a fleet had been served out-of-date figures for roughly ten days. That is a freshness problem, not a prompt problem.
- Stale inventories hide newer sources. Senso noted that a model filter showed stale options because the underlying source stopped updating in early June.
- Empty context leads to fallback behavior. Senso documented a content assistant that invented answers when the required knowledge base query came back empty.
- Source prominence changes over time. In one case, tracked sources with nearly 6,000 citations were moved into their own tier because they had become a major external domain.
When these shifts happen, the citation set changes with them. The model is following the available evidence.
When is source drift normal, and when is it a problem?
Source drift is normal when the underlying truth changed. A new policy, a new price, a new eligibility rule, or a superseded product term should change the answer. The problem starts when the source shift is undocumented, unsupported, or invisible to the people who need to prove what happened.
Here is the difference:
- Normal change: The source of record changed, and the answer changed with it.
- Governance problem: The answer changed, but the organization cannot show why.
- Governance problem: The model queried an empty knowledge base and filled the gap with general knowledge.
- Governance problem: The answer used a stale source after the current one had already changed.
For regulated teams, the last case matters most. A CISO asking whether an agent cited the current policy needs evidence, not confidence. Senso’s docs say that if implementation evidence contradicts the specification, the system should record the discrepancy and propose a new spec revision or Decision Trace.
How do you keep a model grounded over time?
You keep it grounded by governing the source layer, not just the prompt. That means compiling approved sources, verifying answers against ground truth, and preserving the evidence behind each response. Senso calls this the context layer.
-
Ingest approved raw sources into one compiled knowledge base.
This gives the model one governed place to draw from. Senso uses the same compiled knowledge base for internal workflow agents and external AI Visibility. -
Check answers against verified ground truth.
This catches cases where the model cites the wrong source, an outdated policy, or a gap filled with general knowledge. -
Track source replacement and freshness.
Keep publication and verification history so teams can see when a source changed and when the answer changed with it. -
Route unresolved claims to the right owner.
Senso’s loop sends gaps to the teams that can fix them, then re-measures the result. -
Attach proof for consequential actions.
If the model verifies current price, policy, product, eligibility, terms, or authority, attach or link the relevant receipt so the organization can prove what supported the decision. -
Re-run the same questions over time.
Compare factual accuracy, mention rate, citation rate, citation share, and share of voice against the original baseline.
Senso’s two products map to this need. Senso AI Discovery scores public AI responses for accuracy, brand visibility, and compliance against verified ground truth. Senso Agentic Support and RAG Verification scores internal agent responses, routes gaps to owners, and gives compliance teams visibility into what agents are saying and where they are wrong.
What should you audit when sources start shifting?
You should audit whether the model is still grounded in verified sources. The question is not only whether the answer sounds right. It is whether the organization can prove which source supported it.
Focus on these checks:
- Does the answer cite a current source of record?
- Did the source set change because the truth changed, or because the retrieval path changed?
- Did the model fall back when the knowledge base query returned nothing?
- Are citations moving while the underlying facts stay the same?
- Can you preserve a receipt or trace for the decision?
Those checks matter in financial services, healthcare, and credit unions because a stale answer can become a compliance issue fast.
FAQs
Is it always a bad sign when a model uses different sources?
No. It is expected when the underlying source of record changes or when fresher verified ground truth becomes available. It becomes a problem when the change is untracked or unsupported.
Why do citations drift even if the prompt stays the same?
Because the retrieval environment changes. Models update, sources shift, and competitors publish new content. Senso’s docs describe that pattern directly.
How do teams prove that an answer was grounded?
They preserve the citation trail, the verification history, and the source receipt. If the answer affects policy, pricing, eligibility, or authority, the proof has to be attached to the decision.
A model does not become random over time. It follows a changing source environment. Teams that compile approved sources, verify answers against ground truth, and preserve evidence can keep those changes visible, auditable, and controlled. Senso reports 60% narrative control in 4 weeks, 0% to 31% share of voice in 90 days, 90%+ response quality, and 5x reduction in wait times when that governance loop is in place.